
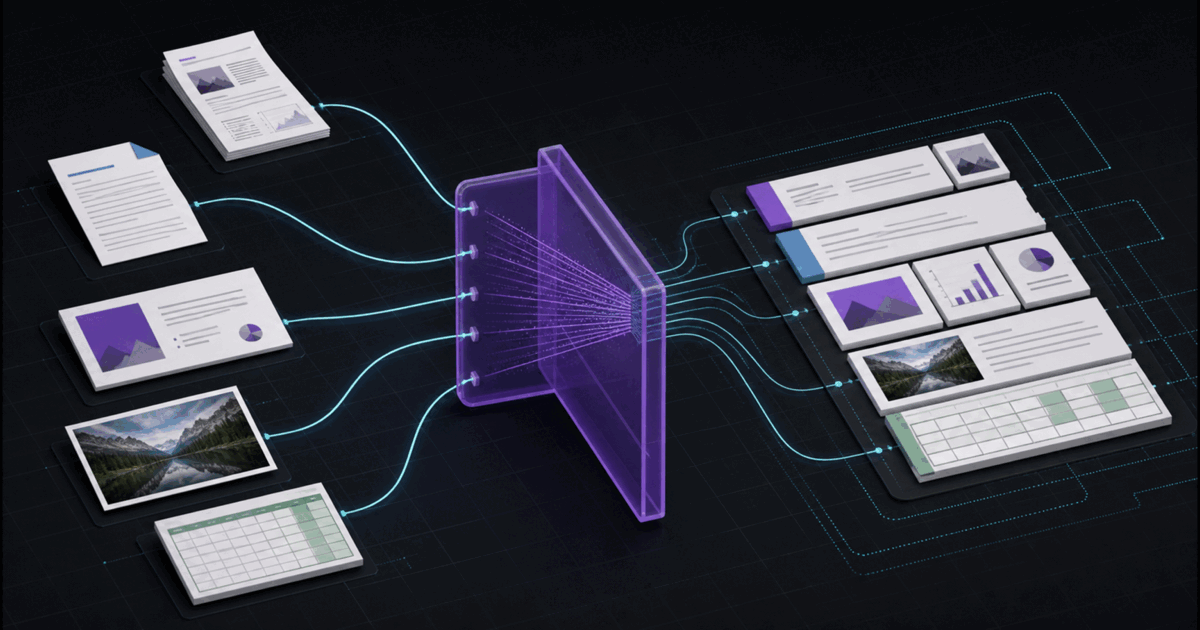
“Upload a document” sounds like one API operation until the first spreadsheet arrives. A PDF exposes pages and positioned objects. A word-processing file exposes sections, styles, comments, headers and embedded media. A presentation adds slide order, z-order and speaker notes. A workbook has sheets, formulas, merged ranges and values that may be stale until a calculation engine opens it. An image has pixels, orientation and perhaps no text at all.
The market correctly treats multi-format ingestion as a category. LlamaParse describes layout-aware and multimodal parsing across many formats. Unstructured emphasizes file-specific transformation while preserving tables, reading order and hierarchy. Docling converts PDF, Office, HTML and images into structured data, including tables, formulas, reading order and OCR. The important signal is not that one parser can accept many extensions. It is that every format carries different structure that downstream systems may need.
A useful document ingestion API therefore makes two promises at once: consumers receive a stable envelope, and the system never erases a native distinction merely because the common schema has no field for it. The contract normalizes access, identity, status and provenance. Adapters preserve meaning.
Normalize the envelope, not the document
The common layer should answer questions every consumer asks: what source arrived, which parser handled it, what units and blocks were produced, where each block came from, whether processing was complete, and which native artifacts remain available. It should not force every source into “pages of text.”
{
  "document_id": "doc_01J7...",
  "source": {
    "name": "quarterly-pack.xlsx",
    "media_type_claimed": "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet",
    "media_type_detected": "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet",
    "sha256": "7a1d6f...",
    "bytes": 481992
  },
  "processor": { "adapter": "xlsx", "version": "3.4.1" },
  "status": "succeeded_with_warnings",
  "units": [
    { "id": "sheet:forecast", "kind": "sheet", "label": "Forecast", "index": 2 }
  ],
  "blocks": [
    {
      "id": "cell:forecast:B17",
      "kind": "cell",
      "unit_id": "sheet:forecast",
      "value": 184200.0,
      "display": "$184,200",
      "formula": "=SUM(B8:B16)",
      "provenance": { "source_sha256": "7a1d6f...", "native_ref": "Forecast!B17" }
    }
  ],
  "native_manifest": "artifacts/doc_01J7/native-manifest.json",
  "schema_version": "cogneris.document-ingestion/1"
}
The envelope is boring on purpose. Stable IDs, hashes, media types, versioned processors, explicit status and a schema version let queues, storage, review tools and extraction services share one lifecycle. The block remains a spreadsheet cell because changing its kind to text would lose the formula, address and distinction between calculated value and display value.
Use a format matrix before designing the schema
A “universal” model built from the first PDF fixture will fail every later format. Start with a matrix of structures that must survive. Treat absence as a deliberate policy decision, not an implementation accident.
| Format | Native unit | Structure that must survive | Common lossy shortcut |
|---|---|---|---|
| Page | Geometry, rotation, reading order, links, annotations, embedded files and object-to-page relationships. | Return plain text in extraction order and call it the document. | |
| DOCX / ODT | Section or flow | Headings, lists, styles, tables, headers, footnotes, comments, revisions and embedded media. | Render to PDF first and discard semantic styles and review history. |
| PPTX / ODP | Slide | Shape hierarchy, z-order, groups, notes, charts, masters and visual reading order. | OCR one slide image and lose editable objects and notes. |
| XLSX / ODS | Sheet | Cell addresses, formulas, cached values, data types, merged ranges, hidden rows, charts and named ranges. | Flatten the visible grid to CSV and silently drop formulas and hidden context. |
| Image | Frame or image | Pixels, dimensions, EXIF orientation, colour profile, OCR regions and derived transforms. | Store OCR text without retaining the source region or transform. |
The formats are not arbitrary containers. PDF is standardized as a page-description format in ISO 32000-2, while modern Microsoft Office documents use the package and markup model standardized in ECMA-376. Their native abstractions differ before any parser runs. A coherent API acknowledges that difference instead of hiding it behind a shared pages[] array.
Separate the content graph from derived views
Most consumers do not want the entire native model. Search may want reading-order text. Retrieval may want chunks. A review UI may want page images and regions. A finance workflow may want typed cells and formulas. Those are projections of one content graph, not competing parse results.
- Source layer — immutable original bytes, detected type, hash, security verdict and container relationships.
- Native layer — the adapter's loss-minimized representation: pages, sections, slides, sheets, cells, shapes, images, attachments and their native references.
- Content graph — versioned units and blocks with typed relationships such as
contains,continues,caption_of,formula_ofandderived_from. - Derived views — Markdown, HTML, plain text, chunks, thumbnails, page renders and extracted business schemas, each linked back to graph nodes.
This layering lets a search index consume a simple Markdown view without making Markdown the archive. When a table parser improves, the system can regenerate the table projection while keeping the source hash, native unit IDs and earlier extraction evidence intact.
Provenance must cross format boundaries
A common schema is valuable only if a consumer can trace every normalized value back to the source. For PDFs and images, that usually means page or frame plus a region. For a workbook, it means sheet plus cell or range. For a word-processing document, it may mean paragraph, table cell, comment or relationship ID. For a presentation, it may mean slide plus shape path.
Use a typed locator rather than cramming every format into bounding-box coordinates:
{
  "provenance": {
    "source_sha256": "7a1d6f...",
    "unit_id": "slide:7",
    "locator": {
      "kind": "shape",
      "native_ref": "ppt/slides/slide7.xml#shape:12",
      "region": { "space": "slide", "x": 0.18, "y": 0.31, "w": 0.64, "h": 0.22 }
    },
    "transform_chain": ["office-native/3.4.1", "slide-render/2.1.0", "ocr/5.8.2"]
  }
}
The optional region supports visual review; the native reference supports exact programmatic lookup; the transform chain explains how the normalized block was produced. This extends the same principle described in bounding boxes as an API contract: coordinates need a named space, origin and transform. A box without those fields is decoration, not evidence.
Errors belong in the response model
Multi-format ingestion creates partial outcomes. One workbook may contain three healthy sheets and one corrupted embedded object. A PDF may parse except for an encrypted attachment. A presentation may yield text while a chart converter times out. A Boolean success forces the API either to discard usable work or to lie about completeness.
| Status or code | Meaning | Consumer action |
|---|---|---|
rejected | Type, size or security policy stopped the source before parsing. | Do not retry unchanged; show the policy reason. |
unsupported_format | The detected type has no enabled adapter. | Route to an alternate converter or request another format. |
password_required | The source is intact but encrypted and no authorized key was supplied. | Request a safe replacement or authorized secret flow. |
failed | No contract-valid output was committed. | Retry only when the code marks the failure retryable. |
succeeded_with_warnings | The response is valid, but named units or features were omitted or degraded. | Consume allowed blocks and surface every warning. |
fidelity_failed | Parsing completed, but a required invariant did not survive. | Quarantine the result; never promote it as complete. |
Each error needs a stable code, affected unit or native reference, retryability, adapter version and safe operator message. Put raw parser traces in protected diagnostics, not in the public response. One adapter crashing should not change the top-level schema or force consumers to learn that library's exception hierarchy.
Fidelity is a test suite, not a demo
A parser can produce plausible text while losing the information that makes a document useful. Acceptance therefore needs per-format fixtures and invariants, including intentionally difficult files. Do not score every format with one “accuracy” number.
- PDF fixtures — multi-column reading order, rotated pages, repeated headers, nested tables, annotations and an embedded file; compare text order and render region overlays.
- Word-processing fixtures — heading hierarchy, footnotes, comments, tracked changes, nested lists, floating images and section headers; assert relationships as well as text.
- Presentation fixtures — grouped shapes, overlap, master placeholders, speaker notes and chart labels; verify z-order and slide-to-shape provenance.
- Spreadsheet fixtures — formulas, cached values, dates, merged cells, hidden sheets, named ranges and locale-specific formatting; compare address, type, formula, calculated value and display value separately.
- Image fixtures — EXIF rotation, multiple frames, low contrast, handwriting and text near edges; verify the transform chain before comparing OCR regions.
Keep golden outputs schema-versioned. When an adapter changes, classify every diff as an intentional improvement, an accepted representation change or a regression. Then run consumer contract tests against the same candidate. A parse result is not safe merely because the parser's own fixtures pass.
Version the contract and the adapters independently
The top-level API should change slowly. Format adapters should improve often. Record both versions so a consumer can distinguish “the response schema changed” from “the PPTX reading-order algorithm changed.” Use additive schema evolution where possible, explicit capability discovery and a deprecation window for fields consumers may rely on.
- Contract version — governs required envelope fields, status semantics, block kinds and compatibility guarantees.
- Adapter version — identifies the format-specific parser and configuration that produced native nodes.
- Transform version — identifies derived operations such as rendering, OCR, table reconstruction and chunking.
- Capability set — declares features actually attempted, supported and preserved for this source.
- Policy version — records limits, disabled features and fidelity requirements applied to the run.
This is also what makes an audit trail for non-deterministic extraction useful. A reviewer should be able to explain an output from persisted source, versions, normalized nodes and citations without rerunning a moving stack and hoping for the same answer.
A production-ready ingestion checklist
- Freeze one common envelope — identity, source hash, detected type, processing versions, units, blocks, provenance, warnings and terminal status.
- Publish a format matrix — name what each adapter preserves, derives, omits and rejects.
- Retain native references — every normalized node points to a page object, paragraph, shape, cell, range, frame or attachment.
- Keep derived views replaceable — Markdown, chunks and page images are projections with their own versions, never the only archive.
- Model partial success — warnings and unit-scoped errors remain machine-readable and cannot be collapsed into a green badge.
- Test fidelity per format — assertions cover structure, formulas, geometry, hierarchy and provenance, not just extracted strings.
- Trace one output backward — start with a business field and reach the normalized block, native locator, source bytes and exact transform chain.
One ingestion contract should make the simple path simple: submit bytes, poll or receive a result, traverse typed content, follow provenance. Its quality is revealed by what it refuses to simplify. Pages remain pages. Slides remain slides. Cells retain formulas. Images retain transforms. Consumers get one API without receiving one flattened, untrustworthy document.