
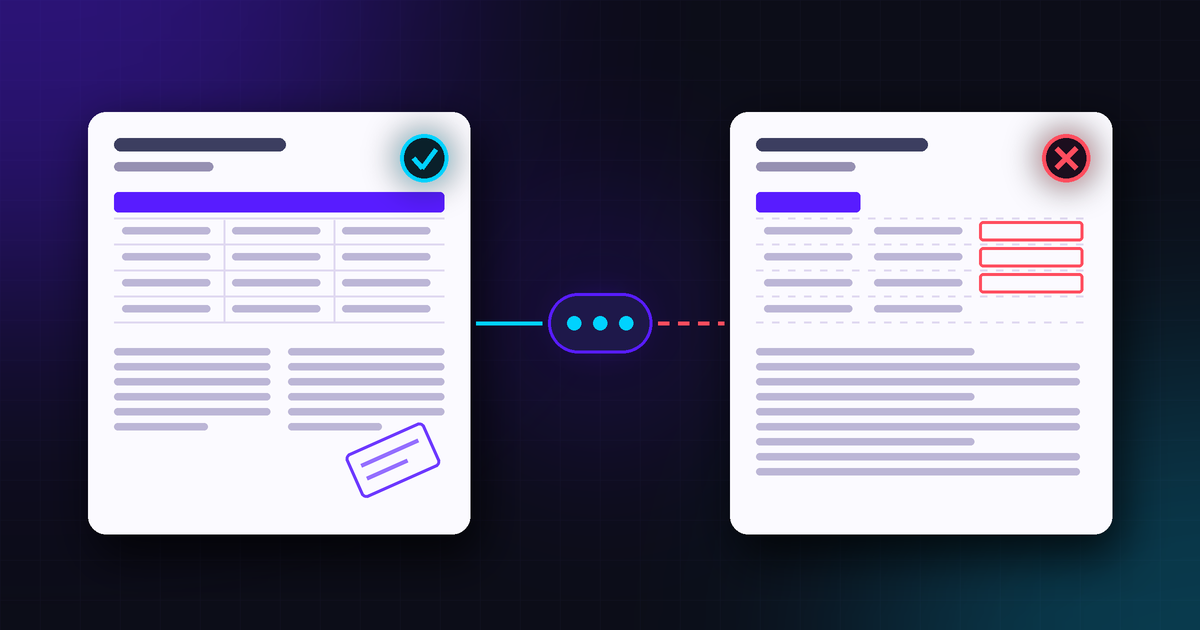
Most document AI post-mortems end in one of two places. Either the input was bad — a dark photograph, a skewed fax, a page half out of frame — or the model got the answer wrong. There is a third place, and in complex document parsing it is the most common of the three: the input was legible, the characters were recognised correctly, and the structure of the page was destroyed somewhere in between.
Layout fidelity is the measure of what survived that step. Not whether the glyphs were read, and not whether the final answer was right. Whether the geometry that carried the meaning is still present in the output. A table that loses its column boundaries still produces text. It produces the wrong relationships between the values in that text, silently, with full confidence.
It deserves its own axis because it fails on its own axis. A parser can hold high character accuracy across a page and still place every value in a nested table one column to the left. Nothing in a character-level score will tell you that happened.
This is not a capture problem
We have argued elsewhere that the right place to reject an unusable photograph is on the device, at the moment of capture, while the person holding the phone can still take another one. That check answers a question about the image: is there enough signal on this page to be worth processing?
Layout fidelity answers a later and narrower question. Given a page that is perfectly legible, did the parser preserve the relationships the page encoded? The two failures are not correlated, and the clearest evidence is the case that has no capture step at all. A born-digital PDF exported from a spreadsheet has flawless capture quality, and it is one of the more reliable ways to break a table parser, because its ruling lines are vector strokes with no fixed relationship to the text runs they appear to contain.
Keeping the two apart is an operational decision, not a taxonomic one. Capture failures are fixed at the edge, by re-shooting or re-scanning. Layout failures are fixed inside the pipeline, by routing the page elsewhere or by parsing it differently. A dashboard that reports both as "document quality" reliably sends the wrong team at the wrong problem, and it does so without ever looking wrong.
Five structures carry most of the loss
Across the document classes that reach production — financial statements, clinical records, freight packets, contracts, filled forms — a small number of structures account for the large majority of layout damage.
| Structure | What the parser does | What it costs downstream |
|---|---|---|
| Nested and merged cells | Flattens the hierarchy; assigns a spanning header to one child column | Every value under the span inherits the wrong label |
| Multi-column text | Reads straight across the page, interleaving two columns line by line | Sentences and clauses fuse; clause-level extraction becomes unusable |
| Charts and figures | Emits axis labels and legend entries as free-floating text | Numbers with no referent contaminate the body text |
| Boxed regions | Merges a callout, sidebar or form box into the surrounding paragraph | Conditional or exception text is read as the main term |
| Rotation and mixed orientation | Leaves a landscape appendix or rotated stamp unnormalised | The page yields nothing, or yields text in an unrecoverable order |
The list is deliberately short. A metric that tries to score every possible layout pathology is one nobody maintains, and an unmaintained metric drifts into decoration. Five classes are enough to separate parsers that differ in ways that matter.
Decide what counts as an error before you score it
The blocking question is not which formula to use. It is what the unit of scoring is, and most teams discover they cannot answer it because their ground truth was never built to.
If your annotated data is a flat list of field values — invoice total, due date, vendor name — you cannot compute layout fidelity at all. Those labels record what the right answer was, not where it lived or what contained it. You can tell that the total was wrong. You cannot tell whether it was wrong because the cell was misread or because the row was misassembled, and those two failures have different fixes.
Scoring layout fidelity requires ground truth that records structure: cell coordinates with row and column indices and span widths, block sequence in intended reading order, and a region type for each block. That is a heavier annotation contract than field values, and it is the real cost of the metric. It is also the same structural record that makes coordinates a usable part of the API contract rather than a highlighting convenience, so the cost is rarely paid for this metric alone.
A score you can reproduce
Report layout fidelity as four numbers, not one. Each corresponds to a distinct artifact of the parse, and collapsing them re-creates precisely the problem the metric exists to solve.
- Cell integrity — tree-edit-distance similarity between the predicted table structure and the annotated one, comparing the grid and its spans rather than the text inside the cells.
- Reading order — a rank correlation between the predicted block sequence and the annotated one, computed per page so a single misplaced appendix cannot be averaged away.
- Region typing — per-class F1 over the region labels: body, header, footer, table, figure, caption, boxed note.
- Orientation — a per-page binary: was the page normalised to its correct reading orientation before anything else ran.
Alongside the four means, publish the worst-performing structure class. That single addition is what turns the metric from a summary into a diagnostic.
{
  "parser": "layout-v4",
  "test_set": "layout-fidelity-2026.08",
  "pages": 1840,
  "cell_integrity": 0.91,
  "reading_order": 0.88,
  "region_typing_f1": 0.94,
  "orientation": 0.99,
  "worst_class": { "name": "nested_merged_cells", "cell_integrity": 0.62 }
}
The aggregate here looks respectable. The worst class is the finding: better than half of nested tables come back with a damaged grid, and no consumer of the aggregate would suspect it.
Declare the test set or the number means nothing
A layout fidelity of 0.91 is not a fact about a parser. It is a fact about a parser and a specific set of pages, and the second half travels badly. A test set that is quietly rebuilt between two measurements produces a comparison that looks like progress and is not.
Declare it along four axes, with a floor on each cell of the grid rather than an overall page count: structure class, source type (born-digital, scan, photograph, fax), page count per document, and script or language. Freeze it, version the identifier, and treat any change as a new set with a new name rather than an update to the old one.
Then keep the failures. The pages a parser gets wrong are more useful than the score, and they are what makes a regression legible six months later. This is the same discipline that separates parsing fidelity from reasoning quality at the benchmark level; layout fidelity applies it one level further down, inside the parsing half.
Where the number belongs
Layout fidelity earns its keep as an infrastructure metric rather than an evaluation artifact, which means it is measured continuously and wired into decisions.
- As an upgrade gate — a parser or model change ships only if no structure class regresses beyond a declared tolerance, which prevents an average improvement from hiding a collapse in one class.
- As a routing signal — pages whose predicted fidelity is low go to a different pipeline or to review before extraction runs, instead of after a downstream consumer notices.
- As a per-tenant series — tenants have different document mixes, so a fleet average can be stable while one tenant's nested-table population degrades steadily.
Tracked next to latency and cost per page, it answers a question those two cannot: whether the pipeline is fast and cheap because it is efficient, or because it stopped doing the structural work.
Three failures the average conceals
One class at the floor. Body text is easy and abundant. A test set weighted toward it will report a high mean while charts sit near zero, because charts are a small fraction of pages and a large fraction of the disputes.
One structural error, many wrong fields. A single merged-header mistake shifts an entire column. Field-level accuracy records this as dozens of independent errors and invites dozens of independent patches, when there is one defect with one fix.
Order that only matters later. Reading-order damage is invisible to single-field extraction and decisive for anything spanning pages — continuation tables, clause references, an appendix that qualifies a term defined forty pages earlier. It surfaces at reconciliation time, far from its cause.
What the metric should change
The immediate effect is narrower post-mortems. When a value is wrong, layout fidelity tells you within one query whether the page was unreadable, the structure was lost, or the extraction was mistaken — three different owners, three different fixes.
The durable effect is on procurement and on upgrades. A parser evaluated only on end-to-end field accuracy over convenient documents will look adequate until the document mix shifts. Measuring the structural layer separately, on a declared set, with the worst class published beside the mean, is what makes that shift visible while it is still cheap to absorb. It also keeps one ingestion contract honest, because a contract that promises stable structure has to be able to demonstrate it.
None of this requires a new model. It requires deciding that structure is a thing you measure, and then annotating for it.