
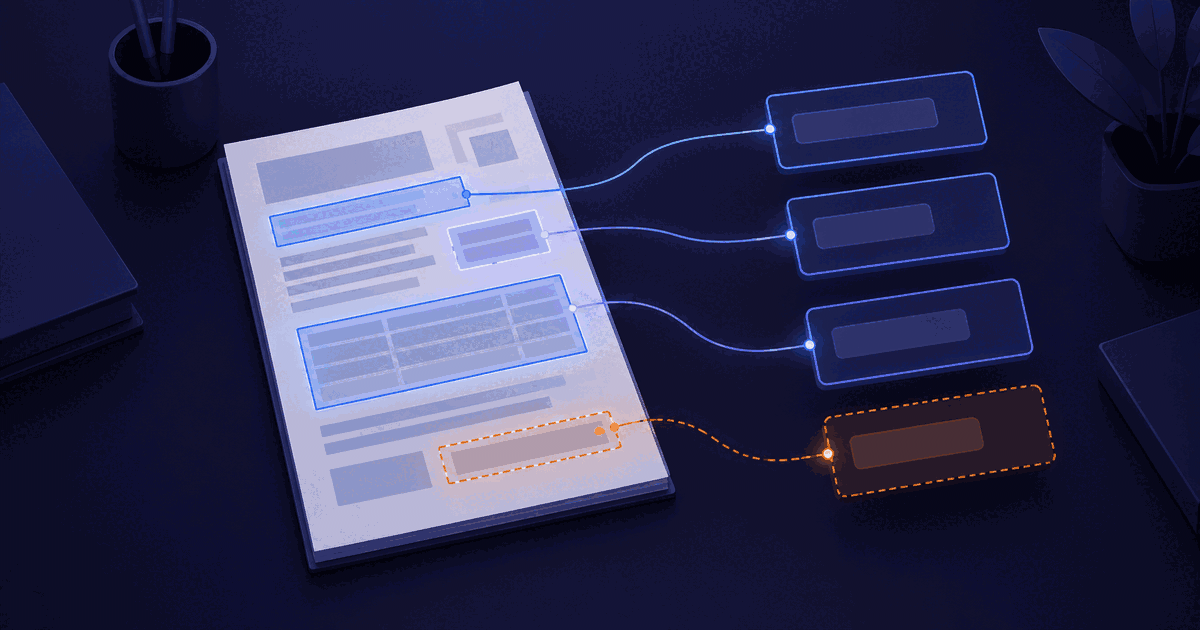
A team receives a new form from a supplier it has never onboarded. The integration already knows how to call the extraction API, but nobody can yet say which fields matter on this layout. The usual response is to start writing a schema from the fields people expect to see. That makes the first extraction call look decisive. It can also make the whole project wrong in a very tidy way.
When the document class is unfamiliar, field discovery gives the team a better starting point: inspect a real document, record the fields that appear, and decide which of those observations belong in a maintained contract. The discovery result is evidence for a schema. It is not the schema itself.
Discovery changes the question
Extraction against a known schema asks a narrow question: “What is the value of these fields in this document?” Field discovery asks an earlier one: “What fields can be found here, and what do they look like?” That difference matters when the target form is new, the layout has changed, or the list of fields was written from memory before anyone sampled the input.
The document tools guide exposes zero-shot discovery as POST /Document/zero-shot. Its example sends a file and returns candidate entries under data.metadata.discoveredFields, each with a name, an observed value and a confidence score. The example uses fields such as supplier and invoice number. Those are useful clues about one document. They do not promise that every relevant field will be found, that the names are canonical, or that the same fields occur on every document in the class.
Think of the call as a structured inspection pass. It can surface vocabulary that the team had not put in its schema and make a first review concrete. Someone still has to decide whether a candidate represents a business concept, whether it is required, and how the system should behave when it is absent or ambiguous.
One document can suggest; a sample can teach
A single file is a poor place to infer what a document class means. It may be a clean export from the most cooperative supplier, the newest revision of a form, or the one example someone had at hand. A field visible there may be optional in the rest of the population. A label may change across revisions. A value may appear only because that particular transaction was unusual.
Choose a sample that reflects the variation the integration must survive. Include more than one issuer or layout when the business receives them. Include revisions that are known to be in circulation, and include ordinary cases as well as the exceptions that cause downstream work. The selection should follow the team’s existing access and handling rules for source documents; discovery is not a reason to widen who can see them.
Keep the sample inventory with the result. Record which document versions were inspected, which layouts were represented and what was deliberately excluded. If the sample is narrow, say so. The goal is not to make the first schema look comprehensive. It is to make its evidence and its blind spots visible before the schema starts driving production decisions.
Keep observation separate from decision
A discovery response contains observations made on an input. A schema contains choices the product will preserve over time. Combining those two stages encourages every newly seen label to become a permanent API field, even when it is a one-off note, a duplicated rendering of another value, or a detail with no consumer.
| Discovery observation | Schema decision |
|---|---|
| A candidate name and the value seen on a sampled document. | A stable field key, with the source label and known aliases recorded separately. |
| A confidence score attached to that response. | An acceptance rule tested against held-out examples and owned by a named team. |
| A field appears in some inspected documents. | Whether it is required, optional, repeatable or conditional, based on the business process. |
| A value looks like a date, amount or identifier. | A type, normalization rule, unit or currency policy, and explicit invalid-value behavior. |
The distinction gives reviewers somewhere to put disagreement. If two suppliers use different labels for the same concept, preserve the raw labels as evidence and choose one canonical key for the contract. If one label names two different concepts, keep them separate until a subject-matter owner resolves the ambiguity. Discovery can show that the question exists; it cannot settle the business meaning on its own.
A schema carries decisions the model cannot make
Before a discovered candidate becomes a field, decide what the field means to a consumer. A stable schema defines more than a name. It states the type, whether the field can be absent, how repeated values are represented, which normalization is safe, and what a downstream system may assume. It also records what to do when the source does not support a clean answer.
Take a total amount. A sample may expose “Total”, “Balance due” or both. The business must decide whether those are aliases, separate obligations or context-specific values. The schema also needs a currency, a representation for a missing amount, and a rule for a document that contains subtotals but no grand total. Calling every amount-like string total would be easy to implement and hard to unwind.
Make ownership explicit as well. A field used to approve payment needs a stronger review path than a field used only to sort a queue. Some fields may contain personal or commercially sensitive information, which changes who should inspect examples and where the evidence belongs. Those are product and governance choices. A score from a discovery response cannot supply them.
Make one candidate concrete
Suppose a response finds invoiceNumber and the value INV-2026-00123. It is tempting to import that pair as a field called invoice_number and move on. But the example establishes only that this label and value appeared on that input. It does not answer whether the field is the supplier’s invoice number, a purchase-order reference printed nearby, or a value whose format changes on credit notes.
For each candidate, keep the raw label, the document reference, the observed value shape and the layout or revision where it appeared. Then ask an owner to decide the canonical key and its aliases. If the source sometimes omits it, record whether that is expected for a document type or a discovery miss. If two candidates look alike, compare their meaning before merging them. If one candidate appears only on a single revision, preserve that fact instead of letting the first sample define every future document.
A compact decision record can say proposed, accepted or rejected, with the reviewer, schema version and reason. A later discovery result becomes a diff against that record: perhaps a new field, a new alias or evidence that the sample missed a variation. It should invite review, not silently change the contract that downstream systems already consume.
Measure discovery separately from extraction
There are at least two ways for this work to go wrong, and one aggregate accuracy number will not distinguish them. Discovery can fail to surface a field that matters, or it can surface a plausible candidate that should not enter the schema. Later, extraction can recognize the approved field but return the wrong value. Those are different failures and need different evidence.
On a reviewed sample, measure field-level coverage: which approved fields were found, which were missed, and which candidates were irrelevant or duplicated. Break the results out by the document variations the team cares about instead of reporting only one average. Then freeze a schema version and measure extraction against it: value correctness, normalization, missing-value behavior and the share of cases that should be sent for review.
Use confidence as a measured signal, not a universal probability. The example response includes a confidence value, but a high score only becomes useful for an automatic decision after the team has checked how scores behave on its own representative and held-out documents. Calibration can differ by field and by document type. If the evidence does not support a threshold, keep the decision in a review path rather than inventing one.
Keep a small set of reviewed examples as a regression fixture when the schema changes. When a new field is added or a name is normalized, rerun the same documents and inspect what changed. That makes a discovery session a reproducible input to design, rather than an anecdote that disappears once the endpoint response is copied into a ticket or notebook.
Discovery is upstream of the extraction method
Two nearby questions already have their own treatment in the blog. Templates versus zero-shot extraction asks which method should fill a target schema when the fields to extract are known. Prebuilt versus custom extraction models asks who should own and maintain the extraction model for that field set. This article answers a step before both: how to examine an unfamiliar document and decide what the target schema should contain.
Field discovery does not choose between a template and zero-shot extraction. It does not train a custom model, compare model accuracy, or replace the validation rules around extracted values. The discovery result may help the team make those later decisions, but they remain separate. Keep that boundary in the design record and the article topic stays useful without repeating the method comparison.
Turn the response into a reviewable contract
A practical sequence keeps the observation, the decision and the production behavior connected:
- Choose a representative sample — include the layouts and revisions the workflow must support, and record the gaps in coverage.
- Run discovery on the sample — save the source document reference, endpoint response and date so a reviewer can trace each candidate back to evidence.
- Normalize candidates deliberately — group true aliases, reject noise and keep the original labels visible instead of silently overwriting them.
- Ask the field owner to decide — set canonical names, types, requiredness, sensitivity, validation and the action for missing or ambiguous values.
- Version the schema and test it — evaluate extraction against reviewed examples, approve changes, and keep the previous version available for comparison.
The output of the sequence is not a perfect schema inferred from one call. It is a versioned contract with an evidence trail: what the team observed, what it decided, which cases it measured, and who approved the decision. That record makes the next unfamiliar document easier to handle because the team can tell a new field from a new spelling and a real requirement from a convenient guess.
Review the fields before they become dependencies
Before a discovered candidate reaches a downstream consumer, check five things:
- Meaning — a business owner can explain what the field represents and distinguish it from nearby values.
- Coverage — the sample includes the layouts where the field is present and the cases where it is legitimately absent.
- Shape — type, normalization, cardinality and null behavior are explicit, not inferred from one example.
- Decision rule — confidence and validation have been measured for the intended use, with a review path for uncertain values.
- Ownership — the team responsible for changing the schema can review the evidence and communicate the version to its consumers.
That is the point at which discovery has done its job. It made the unknown visible and gave the team evidence to decide what to keep. The schema begins where that decision is written down.